
AI Predicted the Peptide Would Work, but the Laboratory Disagreed: Why Molecular Models Still Need Experimental Evidence
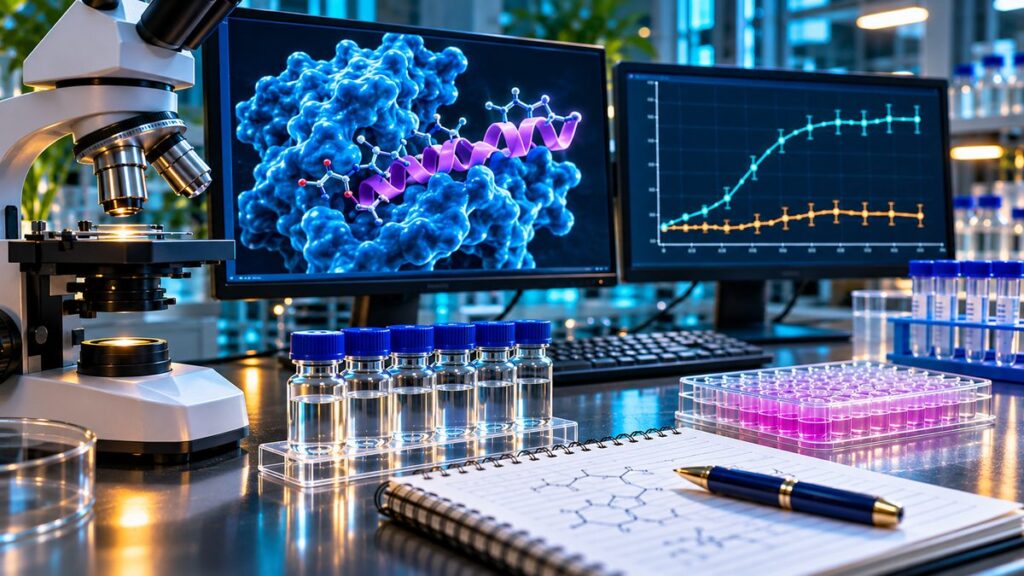
Artificial intelligence can generate a detailed prediction of how molecules might interact long before researchers have observed those interactions in a laboratory. The resulting images can be remarkably convincing. Proteins appear folded into precise three-dimensional structures, binding regions seem clearly defined, and software may assign confidence scores to the predictions.
But a convincing molecular image does not automatically establish that the proposed interaction occurs under experimental conditions.
Consider a hypothetical investigation in which a computational model predicts that a peptide will interact with a particular protein. The predicted structure suggests a plausible connection between the two molecules. Researchers then examine the interaction experimentally and fail to observe the expected response.
Neither finding necessarily means the entire investigation was wasted. The disagreement may reveal a limitation in the prediction, an important biological condition or a difference between what the model calculated and what the experiment measured.
Understanding these distinctions is increasingly important as artificial intelligence becomes part of scientific research, biotechnology development and molecular discovery.
Why AI-Based Molecular Models Have Attracted Scientific Attention
Determining the three-dimensional structures of biological molecules can be technically demanding. Structural information helps researchers investigate how proteins are organized, where potential interaction regions exist and how molecular arrangements may relate to biological function.
Computational systems have become valuable tools for generating structural hypotheses and prioritizing experimental questions.
In May 2024, researchers published AlphaFold 3 in the journal Nature. The system extended computational modeling beyond individual proteins to investigate structures of complexes containing proteins, nucleic acids, ligands and other molecular components.
The study reported improvements across several categories of biomolecular interaction prediction when compared with selected earlier methods and benchmarks.
These advances are scientifically important because they can help researchers explore molecular relationships that would otherwise require extensive preliminary investigation.
However, the original AlphaFold 3 publication also discussed limitations involving molecular dynamics, structural accuracy and certain stereochemical properties.
The central distinction remains important: a predicted structure is a computational result, not an experimentally observed molecular interaction.
A Predicted Binding Structure Is Not Proof of Biological Activity
A molecular model may suggest that a peptide can occupy a particular position near a protein. That prediction concerns a proposed structural arrangement.
Biological activity is a different question.
For a molecule to produce a particular biological response, several conditions may need to be satisfied. The molecule must encounter the relevant biological system, interact with suitable components and influence downstream processes in a way that can be detected using an appropriate experiment.
Binding alone does not necessarily establish functional activation or inhibition.
Some molecular interactions may occur without producing the biological effect researchers originally expected.
Others may depend on cellular conditions that are not represented by a structural model.
Consequently, a model that predicts a plausible interaction cannot independently demonstrate an outcome in cultured cells, an animal model or human participants.
Researchers need experimental evidence matched to the specific conclusion they intend to draw.
The strongest scientific interpretation distinguishes structural plausibility from a demonstrated mechanism.
Why Static Structures Cannot Explain Every Molecular Movement
Proteins and other biological molecules are not permanently frozen in one position.
Under physiological and experimental conditions, molecular structures can undergo movements, transitions and changes in their interactions with surrounding components.
Those changes may influence whether a binding region is accessible or whether a particular interaction can occur.
Computational structure-prediction systems often represent a preferred or likely structural arrangement rather than the complete range of dynamic states that may exist in solution.
The European Bioinformatics Institute’s AlphaFold training materials explain that AlphaFold 3 does not fully capture the dynamic behavior of biomolecular systems and may not predict the correct conformational state in every case.
For example, some proteins adopt different structures depending on whether particular molecular partners are present.
A model may predict a plausible structure while failing to represent a biologically important transition between states.
This does not make the model useless. It means the predicted structure should be interpreted within the limitations of the system that generated it.
Laboratory measurements can help establish whether the predicted arrangement corresponds to conditions relevant to the research question.
How Training Data Can Influence a Molecular Prediction
Artificial intelligence systems learn patterns from data. In structural biology, training resources may include experimentally determined molecular structures and related information.
The quality, diversity and relevance of the training information can influence where a model performs well and where uncertainty remains.
Models may encounter molecular configurations or interactions that are poorly represented in the available data.
Predictive performance should therefore be evaluated on appropriate independent examples rather than assumed to be uniform across every molecular class.
A major concern in machine-learning evaluation is data leakage. This occurs when information from the intended evaluation set becomes available to the model during training or another stage that improperly influences the reported test performance.
The AlphaFold 3 publication described evaluation procedures involving training-data cutoffs and comparisons against more recently released experimental structures.
These procedures help researchers examine whether a model can generalize beyond information already represented in its training data.
Good scientific evaluation requires care because an impressive benchmark score may not fully describe how the system will perform on unfamiliar research questions.
Why Peptide Research Needs a Clear Separation Between Prediction and Experiment
Peptides are molecules composed of amino acids, and scientific investigations involving them can address chemical identity, molecular interactions, biological signaling and other experimental questions.
Computational methods may help researchers explore possible molecular arrangements or identify hypotheses worth investigating.
However, chemical characterization and biological testing remain distinct requirements.
For example, a predicted interaction does not confirm that an experimental sample contains the intended compound. Similarly, confirming chemical identity does not prove that a particular biological mechanism occurs.
Research information resources such as Peptides Minneapolis may be encountered by readers exploring these subjects. As with any scientific information source, molecular predictions should be distinguished from measured laboratory findings and established clinical conclusions.
The appearance of a compound in a computational research discussion does not establish that it is safe, effective or authorized for human medical use.
Each claim requires evidence appropriate to the question being asked.
When Computational Confidence and Experimental Accuracy Differ
Some prediction systems provide scores intended to communicate confidence in particular aspects of a model.
These scores can be useful for identifying regions or relationships where a prediction may be more or less reliable.
However, a confidence score does not automatically establish experimental truth.
A model may predict a protein’s overall structure with substantial confidence while remaining less reliable about the exact orientation of a molecular partner.
Local uncertainty can matter greatly when the scientific question concerns an interaction at a particular site.
Research published in Nature Methods examined how AlphaFold-based structural predictions compared with experimental crystallographic evidence.
The authors found that predictions could match experimental structures closely in many cases, while important differences remained in others.
The study emphasized the value of treating computational predictions as hypotheses that require suitable experimental verification, particularly when precise structural details are important.
This distinction helps prevent a numerical confidence estimate from being interpreted as a universal guarantee of correctness.
Experimental Validation Must Match the Predicted Mechanism
A laboratory cannot evaluate every computational prediction using the same experiment.
The appropriate method depends on what the model claims to describe.
If the hypothesis concerns molecular structure, researchers may consider structural techniques suited to the relevant sample and scientific question.
If the hypothesis concerns binding, an experimental approach capable of assessing that interaction may be appropriate.
If the proposed mechanism involves cellular signaling, investigators must determine whether suitable biological measurements address that specific process.
These approaches provide different kinds of evidence.
A positive result from a cellular assay may be compatible with a predicted mechanism without independently proving every detail of the proposed molecular structure.
Likewise, failure to detect a response may have several explanations, including differences in experimental conditions, model limitations or a genuine absence of the proposed effect.
Researchers should examine the suitability and sensitivity of the selected method before drawing a definitive conclusion.
Scientific validation is most informative when the experiment directly addresses the uncertainty in the original prediction.
Why a Negative Laboratory Result Can Be Scientifically Valuable
Scientific attention often concentrates on experiments that produce strong positive findings.
Yet an experiment that fails to confirm a computational prediction can provide important information.
A negative finding may indicate that the proposed interaction is less likely under the tested conditions.
It may also reveal that the original computational model omitted a relevant feature of the experimental system.
However, a negative result does not necessarily establish that an interaction is impossible under every conceivable condition.
The experiment must be interpreted according to its design, analytical sensitivity and tested circumstances.
Researchers can use disagreement between computational and experimental findings to refine their hypotheses and identify more informative subsequent questions.
This process is a normal part of scientific investigation.
The purpose of computational modeling is not to produce predictions that laboratories must always confirm. Its value lies partly in generating useful, testable ideas.
Why Biological Context Matters Beyond Molecular Shape
The behavior of a molecule depends on more than its geometric structure.
Biological systems involve interactions among many components, and conditions can influence the availability or behavior of a proposed molecular target.
For example, the same receptor may be expressed differently across cell types. A pathway may also behave differently depending on the experimental model.
Consequently, a molecular prediction does not automatically establish what will happen inside a living biological system.
Researchers must distinguish the chemical and structural questions addressed by a model from the broader biological questions requiring experimental investigation.
This is especially important when evaluating investigational metabolic pathways.
Educational discussions of weight-loss peptide research should distinguish computational hypotheses, laboratory models, animal studies and controlled human clinical evidence.
A predicted molecular interaction cannot independently establish clinically meaningful weight changes or the safety and effectiveness of an investigational substance.
Evidence from an approved medicine also cannot be automatically transferred to a different compound merely because the two are discussed within a similar research category.
Reproducibility Is Not the Same as Generating the Same Picture Twice
A computational system can generate similar predictions in repeated runs without proving that those predictions are biologically correct.
Repeated computational output may indicate consistency within the model.
Experimental reproducibility involves a different question: whether an observation can be supported through appropriately designed independent investigation.
The relationship between the two matters when researchers compare model predictions with laboratory results.
One laboratory may use a particular experimental system that produces a measurable response. Another may use different analytical methods or biological conditions.
Different results may require further investigation into the methods and models rather than an immediate conclusion that the prediction is entirely correct or incorrect.
Good scientific reporting identifies the methods, relevant assumptions and uncertainties involved.
Without those details, a highly repeatable computational result can create more apparent certainty than the evidence justifies.
The Risk of Turning Scientific Predictions Into Marketing Claims
Artificial intelligence makes complex scientific ideas easier to visualize and communicate.
However, impressive molecular renderings can also be misinterpreted by audiences who are unfamiliar with the limits of computational models.
A predicted interaction may be described publicly as evidence that a compound produces a particular biological effect.
A preliminary laboratory signal may then be presented as though it establishes a human health benefit.
These transitions introduce unsupported assumptions.
Scientific communication should identify whether a claim comes from computational modeling, direct laboratory observation, animal research or clinical investigation.
It should also explain important limitations rather than relying exclusively on the most compelling illustration or numerical score.
Research organizations have a responsibility to distinguish hypotheses from established findings when communicating technical information.
This distinction supports responsible coverage of artificial intelligence in biotechnology.
Organizational Information Cannot Replace Independent Evidence
Readers examining a scientific website may want to understand who publishes its content and what the organization says about its purpose.
Organizational information can provide relevant context, but it does not independently validate scientific claims.
For instance, Peptides Minneapolis’ about page is a destination for information about that website’s stated identity.
Any claims concerning research findings, testing capabilities, professional qualifications or regulatory status must still be evaluated using appropriate supporting evidence.
A company’s presentation cannot substitute for experimental validation or primary scientific literature.
The same principle applies to artificial intelligence developers. A model’s technical description, commercial presentation or confidence score should not replace independent evaluation of its performance.
Transparency about the source of a claim helps readers understand what has actually been demonstrated.
Questions to Ask Before Trusting an AI-Based Molecular Prediction
Readers can evaluate research involving computational molecular modeling by focusing on the relationship between the prediction and the supporting experiments.
- What exact molecular property or interaction was predicted?
- Which computational model and version produced the result?
- Was the model evaluated against relevant independent experimental data?
- Does the prediction address a static structure or a dynamic biological process?
- What do the model’s confidence scores actually represent?
- Were relevant molecular modifications or environmental factors considered?
- Which laboratory methods were used to test the prediction?
- Did the experimental measurements address the same question as the model?
- Were conflicting results and limitations reported transparently?
- Did the public interpretation remain within the evidence collected?
These questions help separate a plausible scientific hypothesis from a finding established through suitable experimental methods.
They also encourage a more realistic understanding of the strengths and limitations of artificial intelligence in research.
AI Can Accelerate Discovery Without Replacing Scientific Testing
Computational systems have expanded the possibilities for investigating molecular structures and interactions.
They can help researchers explore hypotheses, organize complex information and identify promising directions for experimental work.
However, their usefulness depends on how carefully predictions are interpreted and tested.
A computational model may represent a plausible molecular arrangement while omitting important biological dynamics or producing errors in specific structural details.
Experimental methods remain necessary when researchers need evidence about actual molecular behavior under defined conditions.
The most effective research process does not place artificial intelligence and laboratory science in competition.
Instead, computational predictions help inform experimental questions, while laboratory findings help evaluate and improve the models.
For peptide research and other areas of biotechnology, the essential distinction is between what software predicts and what scientific measurements demonstrate.
An attractive molecular image can begin an investigation. A defensible conclusion requires evidence that supports the claim being made.
Artificial intelligence becomes more valuable when its predictions are treated as scientifically testable possibilities rather than automatic proof of biological activity.