
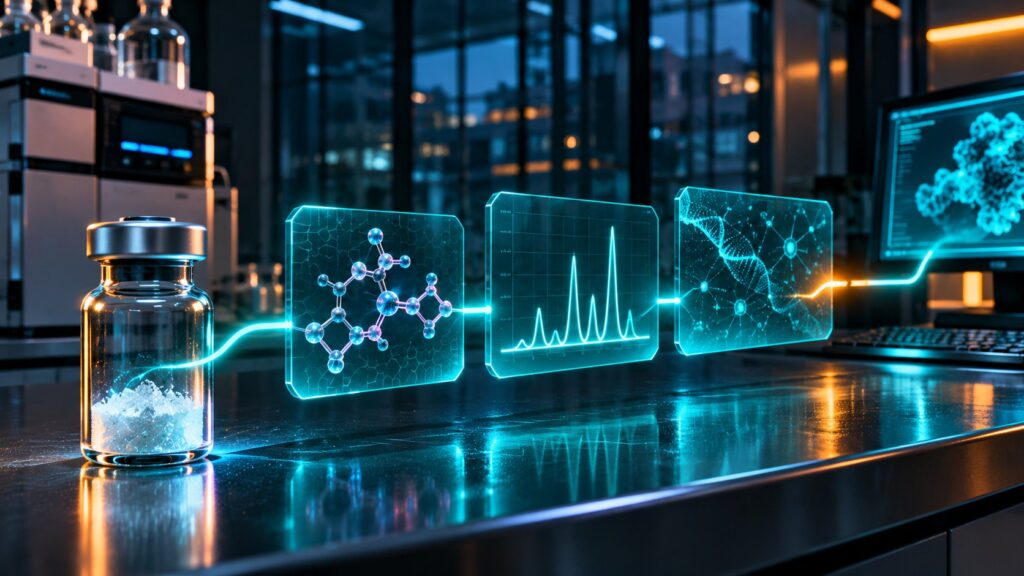
A laboratory can generate thousands of data points in a single day, yet one missing connection between a sample and its records can make an otherwise promising result difficult to interpret. The instrument may have worked correctly. The experiment may have been carefully designed. The researcher may even have obtained an unexpected finding worth investigating. But if nobody can confidently identify which material was tested, which analytical record belongs to it, or how the original observations were processed, the result becomes much harder to evaluate.
This is a growing challenge for research organizations that rely on digital instruments, shared datasets, external suppliers and collaboration across multiple teams. Scientific information can move between laboratory notebooks, spreadsheets, instrument software, cloud storage and published articles. Every transfer creates another opportunity for context to disappear.
The issue is especially important in early-stage molecular research, where investigators frequently study substances whose biological activity is not yet well understood. In these settings, a trustworthy scientific record must connect several separate questions: What was the material? How was it characterized? What experimental model was used? What was measured? And what can the findings actually establish?
A sample identifier is the beginning of the evidence, not an administrative detail
Consider a hypothetical research team investigating the response of cultured cells to a newly obtained reference material. The laboratory receives several containers, each associated with a different lot identifier. One researcher records the incoming material in a spreadsheet. Another enters a shortened sample name into the instrument software. A third later exports analytical results into a shared folder.
Nothing necessarily goes wrong with the experiment itself. The problem appears when the team tries to match the resulting data to the original material. If the shortened name corresponds to more than one lot, the records may no longer provide an unambiguous chain of identification.
A useful sample record therefore needs more than a familiar product or compound name. Depending on the laboratory’s work, it may require the exact chemical identity, lot or batch identifier, source record, receipt information, relevant handling history, analytical file identifiers and a documented relationship to the experiment in which the material was used.
This is not merely an issue of inventory management. Research conclusions may depend on material characteristics that differ between preparations. Two samples described with the same common name should not automatically be assumed to have identical analytical properties.
The National Institutes of Health addresses a related concern through its guidance on rigor and reproducibility. NIH expects investigators to consider authentication of key biological and chemical resources when those resources can influence research results. The principle is straightforward: a reliable experiment requires confidence in the materials on which its conclusions depend.
What digital records must preserve after the instrument finishes its work
Modern analytical instruments can produce extensive electronic outputs. A chromatographic analysis, for example, may generate a signal trace, processed results, instrument parameters and other data that help an analyst interpret the measurement.
A summary document reporting one numerical result may be useful, but it does not necessarily preserve everything required to reconstruct how that result was obtained.
The distinction matters when reviewing a certificate of analysis, often called a COA. Such documents may summarize specified tests and reported findings for a particular material. Their value depends on whether the document can be connected to the correct sample and whether its methods and reported results address the question being asked.
For example, a purity measurement is not interchangeable with a complete chemical identity determination. Nor does an analytical report establish how a substance behaves in a biological system. Different claims require different forms of evidence.
A properly organized digital record helps keep these distinctions visible. It can preserve the source file, relevant metadata, analytical method, processing history, reviewer information and relationship between the reported result and the material tested.
The aim is not to create the largest possible archive. It is to preserve enough trustworthy information for another qualified person to understand what happened without relying on someone’s memory.
The FAIR principles explain why finding a file is not the same as understanding it
In 2016, Wilkinson and colleagues published the FAIR Guiding Principles for scientific data management and stewardship in Scientific Data. FAIR stands for Findable, Accessible, Interoperable and Reusable.
These principles address an important problem in research computing: scientific information should remain understandable and useful after it leaves the original software environment or the hands of its first researcher.
Findability involves more than placing files in a searchable directory. A dataset needs identifiers and descriptive information that allow people or computer systems to locate the correct record.
Accessibility concerns whether the information can be retrieved through appropriate methods, including controlled access where necessary. It does not mean that every scientific record must be publicly available.
Interoperability helps information from different systems work together through shared representations and defined relationships. Reusability requires enough context about data origins, methods and conditions for another researcher to assess whether the information is suitable for a new purpose.
Applied to laboratory research, these ideas suggest a simple test. If a research team exports a dataset today, could a different team member identify the underlying material, measurement method and experimental conditions six months later?
If the answer depends on calling the original researcher, the digital record may be incomplete even if all the files still exist.
Why a molecular name cannot replace a verified research identity
Names are convenient for conversation but can conceal chemical distinctions. Research publications, supplier listings and informal discussions may use abbreviations, historical names or descriptive labels that do not fully define a substance.
Pinealon offers a useful example from short-peptide research. It is commonly described as the EDR tripeptide, made from glutamate, aspartate and arginine. Researchers reviewing a publication need to know that sequence rather than relying solely on a familiar compound name.
The scientific questions surrounding Pinealon also illustrate why chemical identification and biological evidence must be evaluated separately. Published discussions include experiments involving oxidative stress, cell signaling and selected animal models. Those investigations do not establish that the compound improves cognition, sleep or neurological health in humans.
Readers who want to examine the distinction between defined molecular identity, laboratory observations and human evidence can review peptidescostarica.net/blog/what-is-pinealon-edr-tripeptide-research-and-evidence-limits/.
For a laboratory information system, the lesson extends beyond one compound. A record should distinguish the substance’s declared identity from the identity actually supported by available analytical evidence. It should also distinguish observations about a substance from conclusions drawn about its potential applications.
The first distinction concerns the material. The second concerns the strength and relevance of the research. Neither can substitute for the other.
Experimental markers can be meaningful without establishing a clinical outcome
Data interpretation becomes more complicated when a study measures biological markers that are associated with a disease, tissue or physiological process.
Consider cartilage research. Investigators may examine molecules and transcription factors associated with cartilage-cell behavior and extracellular-matrix formation. These measurements can help describe what happens in a controlled experimental model.
However, a change in a cellular marker does not automatically prove that a substance repairs damaged tissue or produces a useful result in a person.
Cartalax, a short peptide commonly associated with the amino-acid sequence Ala-Glu-Asp, provides an example. Laboratory discussions involving Cartalax examine cartilage biology and markers such as SOX9, aggrecan and type II collagen. These are scientifically relevant measurements, but they must be interpreted within the experimental systems that produced them.
The distinction is explained in an overview of Cartalax research and experimental evidence, which separates cartilage-related laboratory questions from unsupported human treatment conclusions.
For data management, this means recording the exact experimental endpoint instead of replacing it with an attractive summary. A dataset labeled as a change in gene expression conveys something materially different from one labeled as tissue repair.
The first describes a measurement. The second suggests a broader biological outcome that would need separate supporting evidence.
Good scientific reporting maintains that boundary even when the early results appear interesting.
A digital research system should preserve experimental context, not just positive results
Many laboratory databases are organized around samples, dates and files. That structure is useful, but researchers may also need to preserve the context that makes their findings interpretable.
Relevant information can include the model or system studied, control conditions, analytical method, inclusion and exclusion criteria, measured outcomes, and the distinction between technical and biological replication.
It is also important to preserve results that do not support the original hypothesis. If only favorable measurements remain easy to retrieve, later reviewers may receive a distorted impression of the complete investigation.
The NIH’s rigor and reproducibility guidance emphasizes sound experimental design, transparent reporting and authentication of important research resources. Those expectations cannot be met by file organization alone. They depend on decisions about study design and the quality of the accompanying records.
In practice, a useful system links the original data to the assumptions and procedures under which they were collected. Researchers should be able to distinguish unprocessed observations from corrected, normalized or otherwise transformed outputs.
That separation makes it easier to review unexpected results. It also reduces the risk that a later analyst will mistake a processed figure for an independent original measurement.
When the category itself is wrong, the data may be interpreted incorrectly
Research classification errors are not always caused by missing records. Sometimes the underlying description of a substance is inaccurate.
SLU-PP-332 is a useful example because it is frequently discussed alongside peptides, although it is a synthetic small molecule rather than a peptide. Published preclinical research has examined its effects on estrogen-related receptor signaling and pathways connected with cellular energy metabolism.
Calling it a peptide can distort the scientific description before any experimental results are considered. Calling it an established replacement for exercise would create a different and more serious error, because findings from laboratory and animal models do not establish equivalent outcomes in people.
Researchers examining these distinctions can consult this analysis of preclinical findings, which identifies SLU-PP-332 as a small-molecule research compound and explains the limits of the evidence.
The broader data-management lesson is that classifications should be grounded in defined characteristics. Search tags, category labels and commonly repeated descriptions are not substitutes for accurate scientific metadata.
When a database incorrectly groups chemically different substances, researchers searching across records may also draw misleading comparisons between experiments that were never measuring equivalent systems.
Three questions to ask before trusting an automated research summary
Automated analysis can make research records easier to search and compare. Software can organize experimental files, extract metadata, identify repeated sample names and summarize patterns across datasets.
These capabilities can save time, but they do not eliminate the need to evaluate what the records actually establish.
First, can the reported result be connected to an identifiable source? The source may be an instrument file, a laboratory record or a published investigation. A numerical conclusion without a traceable origin is difficult to evaluate.
Second, is the description faithful to the measured outcome? A change in cellular activity should remain described as a cellular observation. A result in an animal model should not silently become a statement about human performance.
Third, has the system preserved uncertainty? Incomplete data, limited replication, study-design weaknesses and differences between experimental models should remain visible rather than disappear during summarization.
These are important checks for human-written reviews as well as automated systems. A computer-generated explanation is not necessarily more reliable simply because it is neatly formatted or supported by a large number of source files.
The value of analytical technology depends partly on whether it helps users identify the boundaries of the evidence, rather than hiding those boundaries behind a confident conclusion.
What better laboratory information practices look like in daily work
Improving research records does not always require replacing every existing system. Many laboratories can begin by examining where identifying information is lost between their current tools.
A research team might discover that the receiving log uses full sample identifiers while instrument exports record only abbreviated names. Another team might find that reports are stored separately from the methods used to generate them. A third may have difficulty identifying which analytical files support specific figures in a draft publication.
These problems can be addressed by defining common identification rules and responsibilities across the workflow.
- Assign clear sample and lot identifiers, and retain their relationship to original source records.
- Define the minimum metadata needed to interpret each type of experiment.
- Preserve original analytical outputs separately from processed summaries.
- Record which method, system and version produced the reported measurement.
- Keep experimental conditions and control information associated with the results.
- Document corrections so that reviewers can distinguish the original record from later changes.
- Test whether another qualified team member can retrieve and interpret a completed study without informal explanations.
These practices are not a substitute for appropriate laboratory quality systems, validated methods or institutional requirements. Their purpose is to make scientific work easier to examine and reproduce.
A small, consistently applied identification standard can sometimes be more useful than an elaborate software platform with poorly defined responsibilities.
The most valuable research record is the one another scientist can understand
A strong experimental result should remain understandable after the people who produced it have moved to other projects. Its sample identity, analytical evidence, study conditions and limitations should not depend on private recollections or assumptions hidden inside disconnected files.
Scientific progress depends on asking whether observations can be checked, reproduced and extended. Digital systems support that goal when they preserve the information needed to answer those questions.
For emerging areas of molecular research, the distinction between measuring a substance, observing a biological response and demonstrating an outcome is especially important. Each step answers a different question. Each step also has its own evidence requirements.
The laboratory data trail is therefore more than a paperwork exercise. It determines whether a scientific observation remains an isolated result or becomes a finding that other researchers can meaningfully investigate.